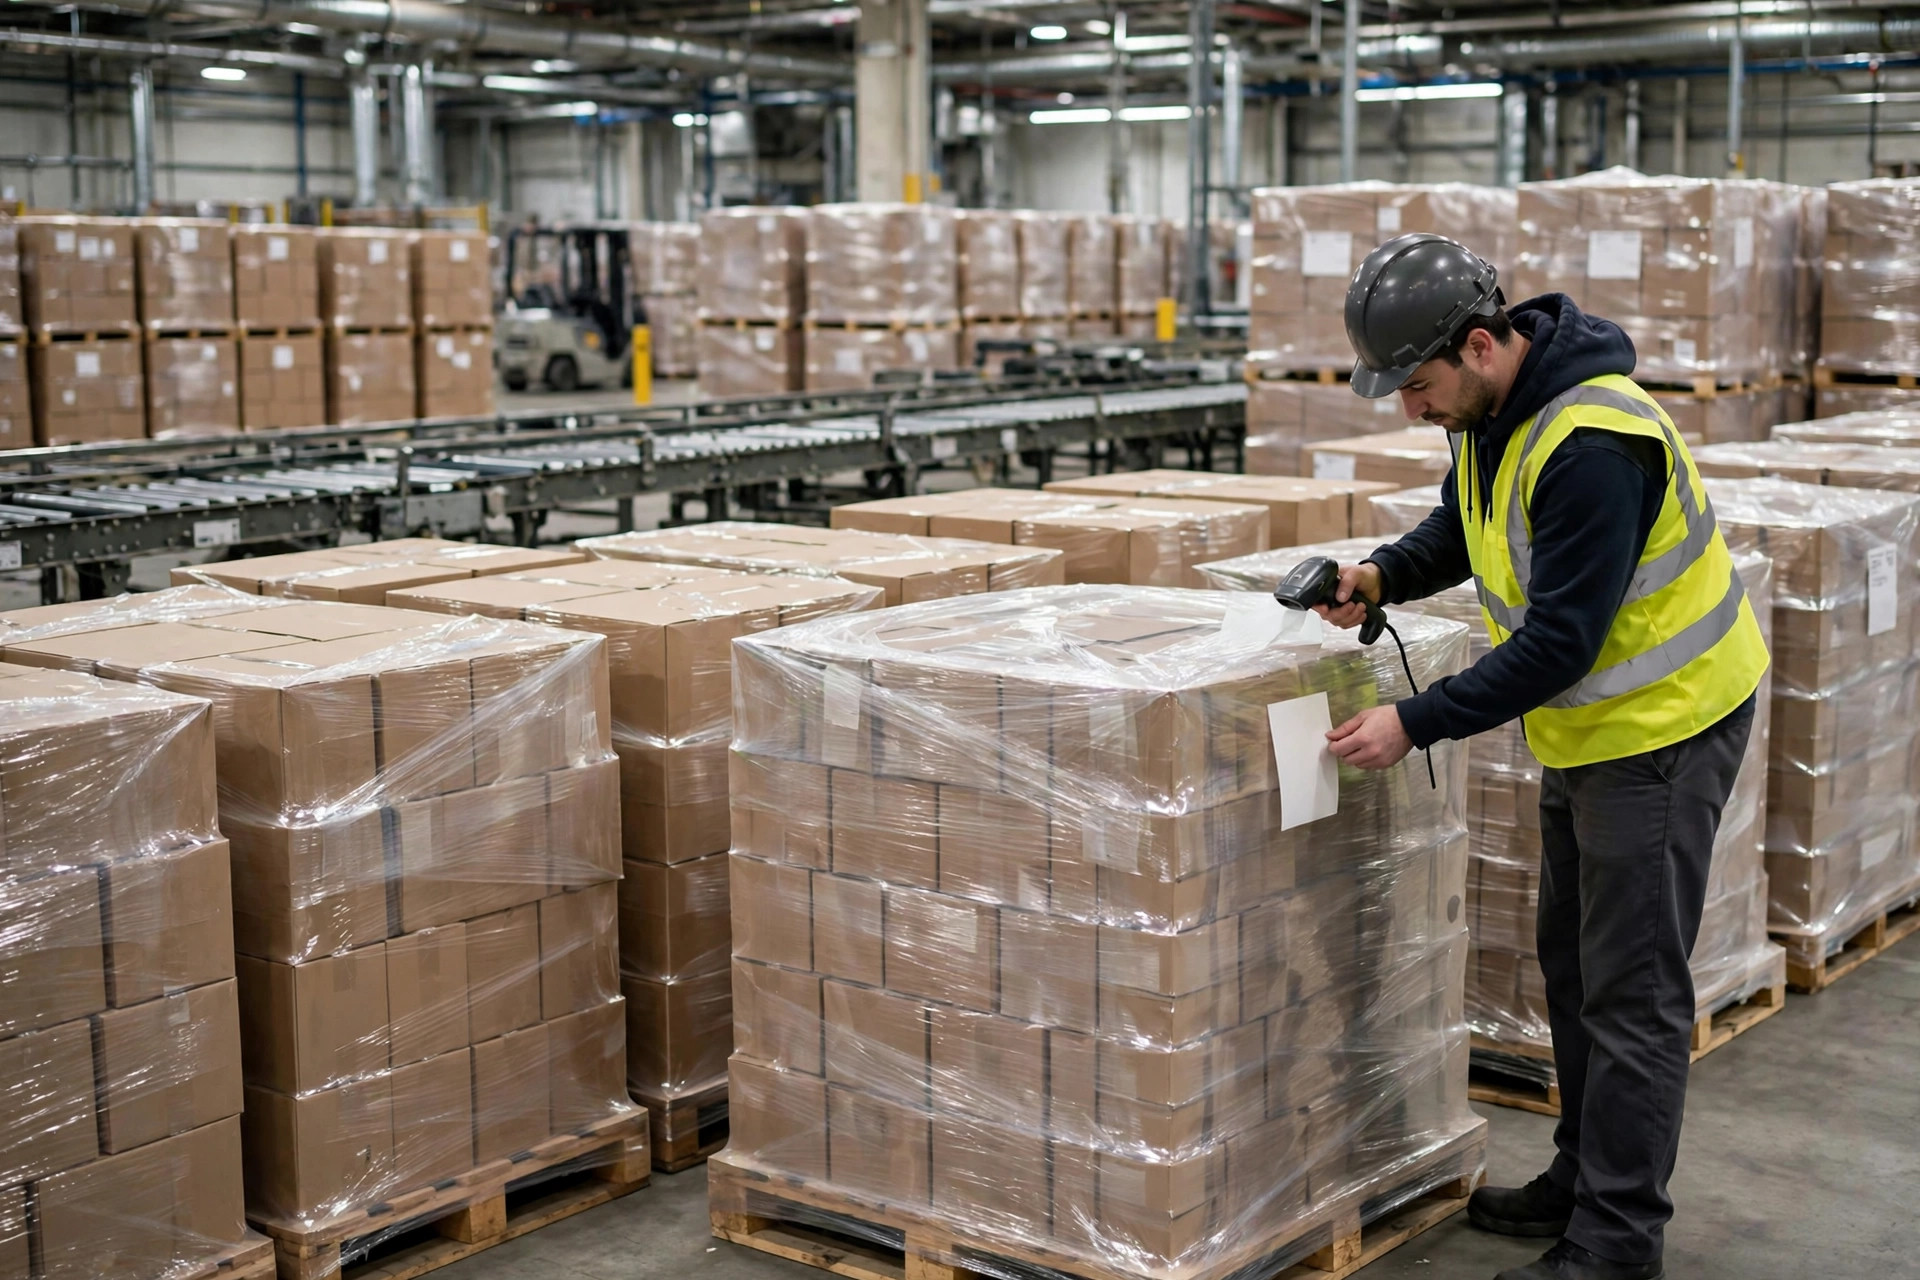
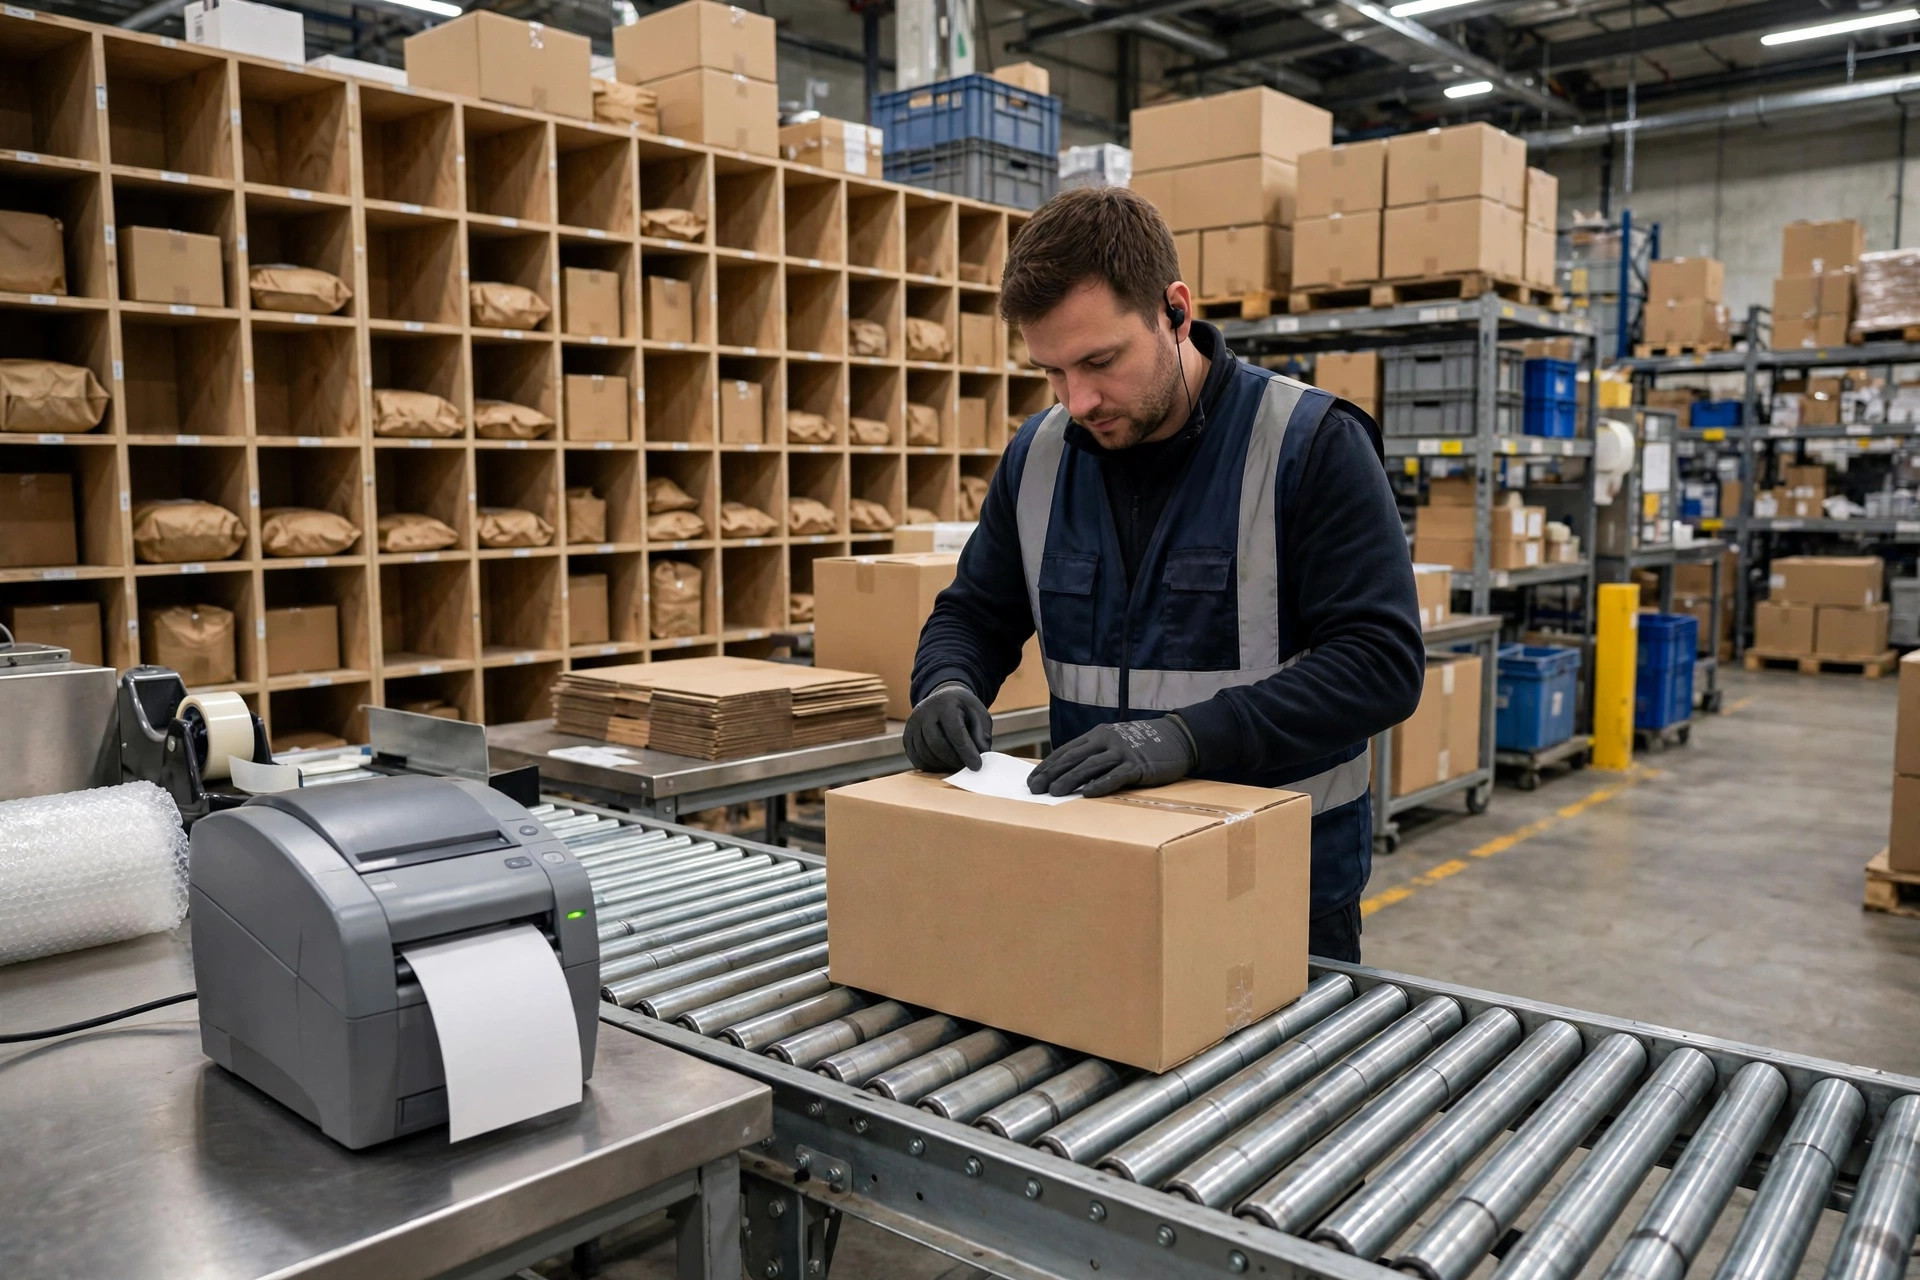
In 2019, at a 3PL warehouse in Ontario, California, I watched this scene play out: thirty or forty packages piled up at the packing station, an operator scanning each one with a handheld, the system showing "label created" for every order — but only half the labels were actually sitting on the table. The printer was feeding paper just fine. It was just... short. Customer service calls were already coming in: buyers asking why their tracking never updated. That afternoon we tore through the entire chain, and in the end the carrier had nothing to do with it. Our own retry logic didn't carry an idempotency key. A timed-out request had actually succeeded on the carrier side; the system assumed failure and fired again. The second call returned the same label, overwrote the first record, and the first package had long since shipped with the other printed label stuck on it. The one that didn't reconcile was the overwritten label.
Here's my verdict up front: when carrier label APIs "lose" labels, 90% of the time it's not the carrier's fault — it's your retry logic and your state machine. Of the remaining 10%, about seven parts are the print queue and three parts are the carrier side. Sounds aggressive? I've spent twenty years on US warehouse floors and integrated more label APIs than I can count on two hands. The root cause is always one of the six steps below. Here's a debugging chain from symptom to root cause, in order. One afternoon is enough to pin it down.
Don't Blame the Carrier Yet — Check Your Request Logs
When it breaks, step one is always the logs. Not the carrier's dashboard — your own system's record of whether the label request actually went out and what the carrier sent back.
Where to look: your WMS or middleware's API log table. What healthy looks like: every call gets a record with a timestamp, order number, request body, response body, HTTP status code, and latency. Check three things.
First, are the full request and response persisted? Plenty of systems only store "success/fail" and throw away the response body. That's a black box. Debugging lost labels without complete request/response pairs is basically guessing. The worst setup I ever saw logged only the order number and "OK" — when things broke, the team had to reconcile order by order in the carrier portal. That turned one afternoon into three days.
Second, were there timeouts, and how many retries? Timeouts on label APIs are normal; carriers get slow during peak, sometimes beyond 10 seconds. The real question: did you retry after the timeout, and did the retry carry an idempotency key? A timeout is not a failure — the request may well have succeeded on the carrier side while your system never got the response. A blind retry then prints two labels — or worse, two labels sharing one tracking number, with your system only recognizing the second one. The first label becomes a ghost: physically on a package, invisible to your system.
Third, does the tracking number in the response match the one stored in your system? Some integrations confuse the carrier's master tracking number with the package-level number and store the wrong field. The label isn't lost — you're looking in the wrong place.
If your logs are complete, this step alone exposes the problem 80% of the time. If your logs are incomplete, fix the logging before you debug anything else — without data, every conclusion is superstition.
If One Order Hits the API Twice, How Many Labels Come Out?
Step two: idempotency. This is the disaster zone, and it's the root cause of the story I opened with.
What healthy looks like: the same order number hitting the API any number of times produces exactly one valid label on the carrier side; repeat calls return the first result instead of minting a new label. That guarantee comes from an idempotency key — usually the order number plus a business-unique identifier, sent with the request.
Where to look: your API wrapper — does the label request actually transmit an idempotency field? Most carrier label APIs support one (check the carrier's latest docs for the exact field name), but plenty of warehouse integrations never send it. The sneakier variant: you send one, but at the wrong granularity. Using "order number + timestamp" as the key, for example — the timestamp differs every time, so it's the same as sending nothing. Every retry mints a fresh label.
How to verify: take a lost-label order and count how many times the API was called in the logs, and whether each call returned the same tracking number. Two calls returning two different tracking numbers, with only the second stored in your system — the first tracking number's label is your "lost" one. It really exists, stuck on some package. The package shipped; your system doesn't know it. What customer service sees is "label created but no tracking updates."
And one database-level backstop: the label/tracking number column needs a uniqueness constraint. Without it, duplicate writes never error out — dirty data piles up silently, and by the time you notice, nothing reconciles. Adding that constraint costs nothing and pays off immediately.
Label Generated, Status Never Written Back: Check Your State Machine
Step three: async callbacks and the state machine. Some label APIs are asynchronous: you send the request, the carrier replies "accepted," and the actual label file and tracking number arrive via callback seconds or minutes later.
What healthy looks like: the order status flows cleanly — say, pending → creating → created → printed — each transition timestamped. If the callback hasn't arrived, the order should sit at "creating," not somehow become "created."
Where to look: the status transition log. Watch for skipped states: the callback never arrived, yet the status reads "created." That's usually an over-optimistic polling job or frontend logic that marks success the moment the request is sent, never waiting for the callback.
The nastier variant: the callback arrived, but your callback endpoint errored — a signature verification failure, a database lock timeout — so the carrier shows "delivered" while your side never persisted it. Each side tells its own story. Check the callback endpoint's error logs; the evidence is almost always there. Nobody was reading it.
My verdict: the state machine is the single most worthwhile thing to get right in the label pipeline. A state machine that allows skipped states is no state machine at all.
The Printer: The Most Wronged Scapegoat
First three steps clean? Look at printing. Zebra printers drop jobs more often than you'd think.
What healthy looks like: the label file enters the print queue, the printer spits out sheets one by one, and each sheet gets a print confirmation. Where to look: the print server's queue log — is each job "completed" or sitting in "error/cancelled"? Zebra printers have a classic habit: ribbon or label stock runs out, the printhead overheats, and instead of telling anyone loudly, the job just stalls in the queue while the frontend says "sent." The operator sees no paper, assumes the system never created the label, and hits print again — and without a print-confirmation handshake, that prints a duplicate.
Another classic: a network printer drops and reconnects, and the backlog in the queue all comes pouring out at once. The operator tears off a few, slaps them on, and the rest get mixed together — misapplied and missed labels everywhere. That's why my prevention checklist insists on a print confirmation receipt: the printer acknowledges each sheet, and only then does the system advance the status to "printed." A print without a receipt is a print that never happened.
The Carrier Side: Rate Limits and Address Validation, Silently Swallowed
Finally, the carrier. The honest conclusion: genuine carrier-side causes are rare — a few times a year at most. But they're the hardest to investigate, because the problem isn't in your hands.
Where to look: the carrier developer portal's API call records and error codes. Focus on two categories.
First, rate limiting. During promo season and peak, your QPS exceeds the account quota and the carrier rejects the request. Some return a clean 429; others — I'll say it plainly — one major carrier returns 200 on certain endpoints when throttled, with a quiet error message tucked inside the body. If your code only checks the HTTP status, it believes the label was created. It wasn't. That's a silent failure; when investigating, read the response body, not just the status code.
Second, address validation failures. US addresses are fiddly — one wrong digit in the apartment or suite number, a ZIP+4 mismatch, and the carrier-side validation rejects the order. That should come back as a clear address error, but some integrations swallow validation errors as generic exceptions, logging only "label creation failed." The operator sees the failure, keys the order in manually — with a slightly different address than the system record — the package ships, and nothing reconciles. For this category, front-loading address validation matters ten times more than post-mortem debugging.
I won't quote specific rates or throttle numbers here; carrier policies change fast, so go by the latest published policy on their official site.
Reconcile Daily: The Last Safety Net, and the First Thing You Should Have Built
Step six, and the one I most want you to ship tomorrow: reconcile your label count against the carrier's bill every single day.
The logic is simple: yesterday's "label created" count in your system should equal yesterday's label count on the carrier's invoice. Where they differ, the gap is your lost labels — whichever step of the chain swallowed them, the numbers don't lie.
How to do it: write a daily reconciliation job that pulls the carrier's invoice or usage report overnight (most carrier portals export one) and matches it record by record against your system's label records by tracking number. The exception list lands in operations' and IT's inbox every morning. The first run may scare you — that's historical debt surfacing all at once, which is good. It means the mechanism was running naked before.
I recommend two alert tiers. Business-level: alert if no labels are created for 10 minutes during operating hours — a packing station can't go 10 minutes without a single label under normal operations, so a trigger almost certainly means the API is down. Reconciliation-level: escalate to a human if the daily exception count exceeds 5. Tune the thresholds to your volume, but have thresholds. Monitoring without thresholds is not monitoring.
The Prevention Checklist: Do These Five and Lost Labels Basically Disappear
Debugging cures the disease; prevention keeps you healthy. Five items, ranked by bang for the buck:
| Item | What to do | Cost |
|---|---|---|
| Timeout retry policy | Retry on timeout only, always with an idempotency key; max 3 retries with exponential backoff | Half a day of dev |
| Tracking-number uniqueness | Unique index on the tracking number column; duplicate writes fail loudly | Minutes |
| Tighten the state machine | No skipped states; orders park at "creating" until the callback lands, then escalate to manual review on callback timeout | 1–2 days |
| Print confirmation receipts | Printer acknowledgments drive the status transition; no receipt means "not printed" | Needs print-server cooperation |
| Daily reconciliation job | Auto-compare overnight, email the exception list, escalate past 5 exceptions | 1 day |
Also: keep complete request/response logs for at least 90 days. Don't complain about the storage. When a lost-label dispute lands on your desk, those logs are your evidence.
One real question to leave you with: tonight, go check how many of your orders hit the label API more than once in the past month. That number is the upper bound of your ghost-label population. You might lose some sleep over it — but that's still better than being woken up by customer service.