The worst WMS go-live I ever saw went like this: at noon on launch day, pickers' RF guns couldn't pull task lists, and 40 people stood in front of racking with nothing to do. The owner was pounding his desk, IT was blaming each other in a conference room — because nobody had decided who gets to call the shots when things break.
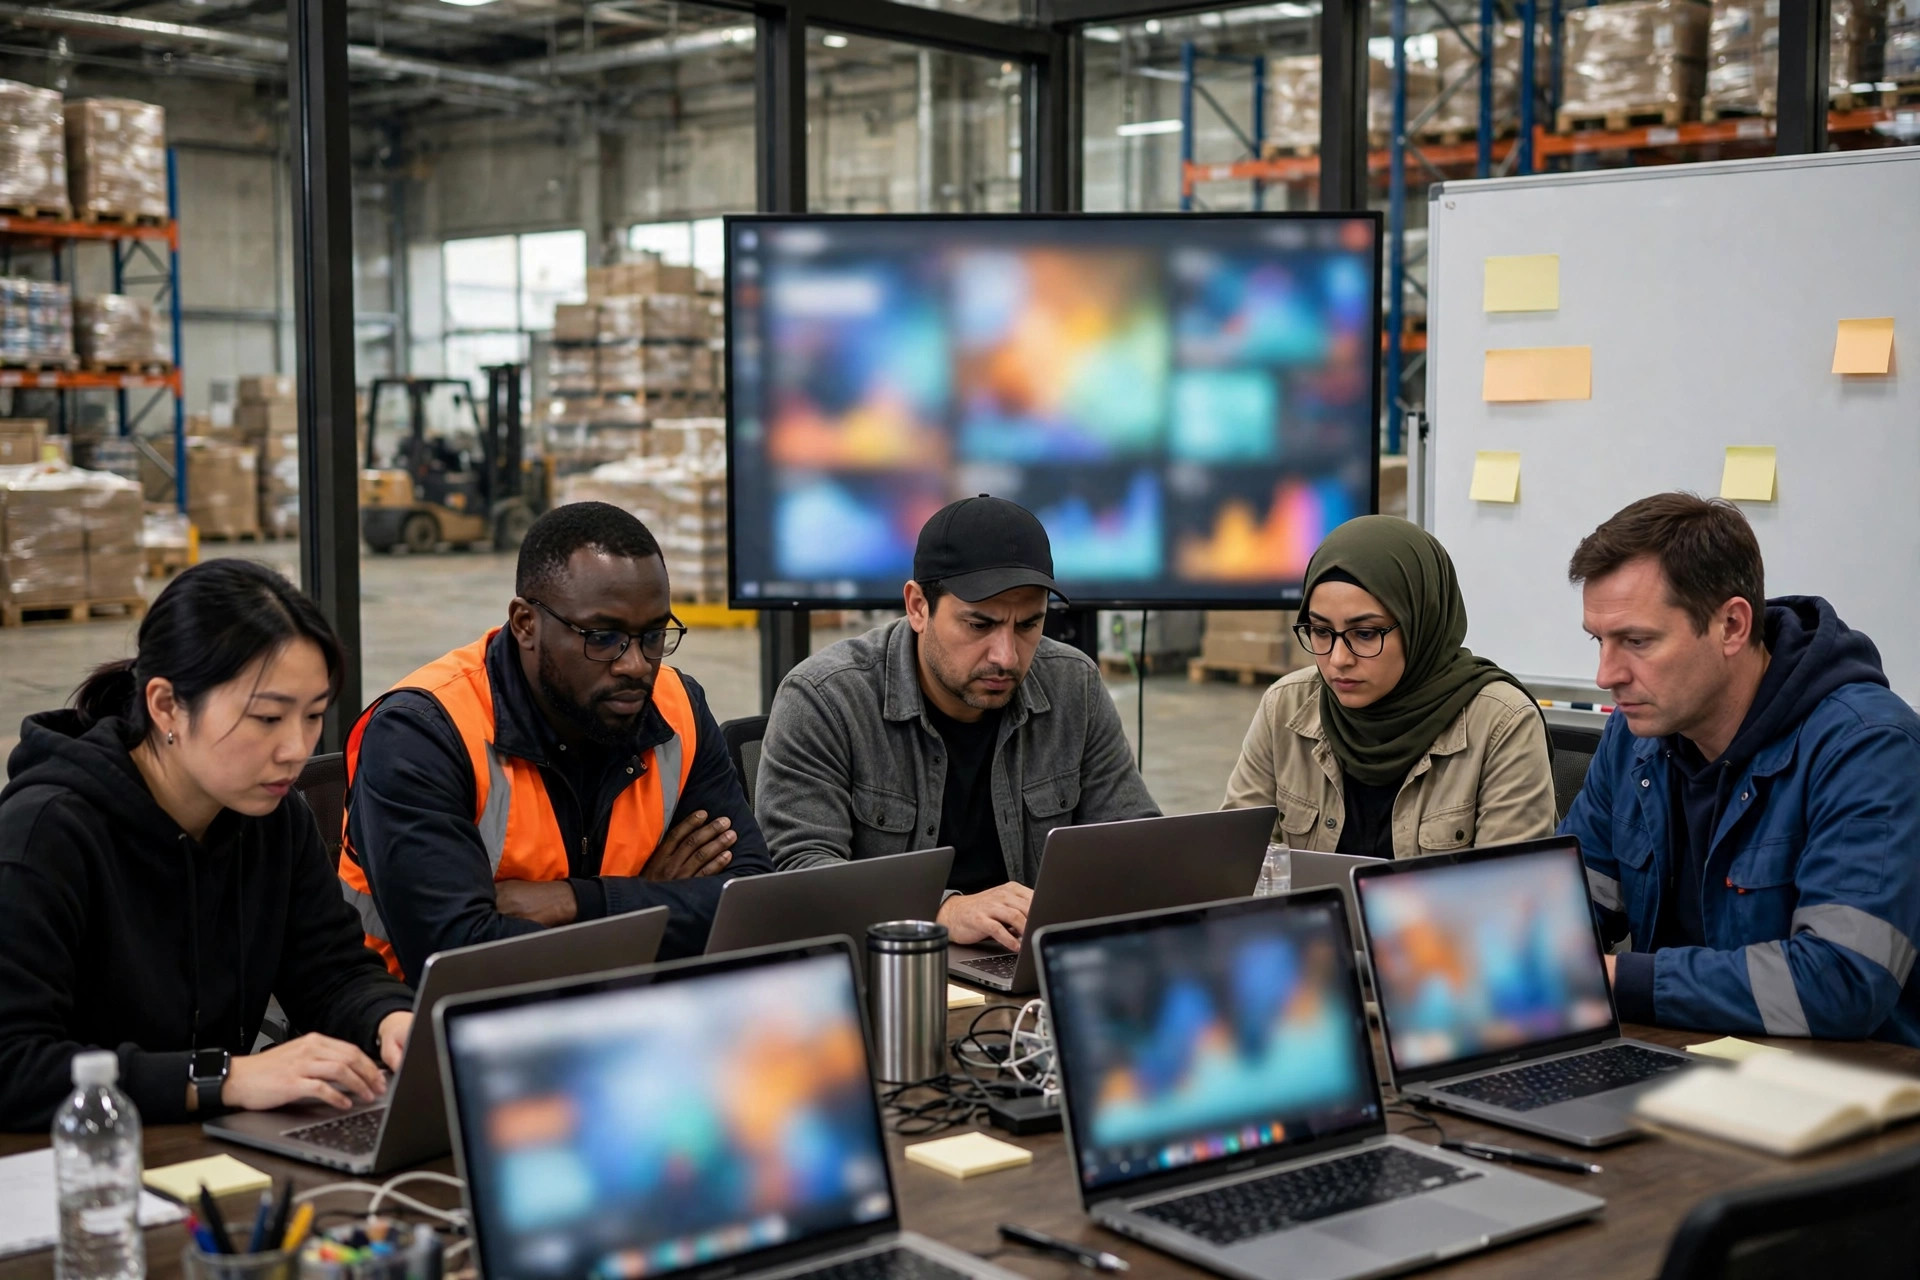
After that I learned my lesson: for week one of any system launch, the warehouse needs a war room. Not a meeting room — a command post. Who sits in it, what tools they bring, and what rhythm they run on all get decided before go-live. Here's the playbook I've refined over several launches. Steal it.
Three launches I watched fail — all on "nobody could call it"
Three real lessons first, and you'll see why the war room is non-negotiable.
The label paper. On day two, every printer stopped — not a system bug. The label paper ran out. Admin had stocked it based on the old system's usage, but the new print format doubled consumption. Thirty warehouse staff waited all morning for a courier delivery. The war room checklist has carried this line ever since: stock three days of consumables.
The interface died at 2 AM. The ERP order feed dropped at 2 in the morning and the WMS stopped receiving orders. The on-call IT was new and didn't know who held the interface restart rights; he @everyone'd the group chat and it took 40 minutes to find the right person. In those 40 minutes, the 6 AM wave plan fell apart. Since then the roster names names and phone numbers, pinned to the war room wall.
The owner took command himself. On day three an S2 hit: IT needed 4 hours to fix, ops couldn't wait. The owner stormed onto the floor, bypassed the war room, and started redirecting the workflow himself — which conflicted with the system logic and created 200 exceptions that day. After that I set an iron rule: in week one, the floor takes orders from exactly one voice — the war room. Owners with opinions say them inside the war room.
Three failures, three ways to die, one root cause: at the critical moment, nobody could decide — or the wrong person did.
The 5 people who must be in the room
Wrong people, and the war room is just a place to argue. These five roles are non-negotiable:
The floor commander (one person, final say). Must be an ops leader who knows the business — not IT. They get exactly one power: within 5 minutes of an incident, decide "keep going" or "stop." Week one cannot survive committee decisions.
The WMS implementer, on-site. When a config bug hits, only they can fix it on the spot. Write on-site support into the contract for go-live week — I've watched remote-only support fail.
The IT / integration lead. A WMS is never an island: the ERP order feed, carrier label API, and billing interfaces can each halt the warehouse if they drop. This person holds monitoring and restart rights for every interface.
Shift leads from the floor. One each from picking, receiving, and audit. They're the system's human sensors — the first to feel a laggy screen or an awkward workflow. Give them a direct channel to report, not just a relay role.
The scribe and escalation manager. Every issue gets ticketed, severity-rated, and tracked to closure. This person decides what waits until tomorrow and what escalates now — the room's order depends on them.
One line: if the war room is full, the floor stays calm.
The 48-hour pre-launch checklist
The war room gets built two days before launch, not the morning of. Check them off:
- Data freeze: the exact moment the old system stops taking entries, synced company-wide. Before freezing, validate three things: SKU master data, locations, and inventory balances. If any of the three don't reconcile, you don't launch.
- Print consumables: shipping labels, barcode labels, ribbons — stock three days' worth. Laugh if you want; I've seen a warehouse idle on day two waiting for a label-paper delivery.
- Rollback drill: rollback isn't "we'll go back to the old system if it gets bad." Write it down: trigger conditions, who gives the order, how data flows back, how many hours the old system needs to recover. Walk through it at least once on paper before launch.
- Shift roster: week one runs two 12-hour shifts a day (day and night covering round the clock), seven days straight. Names and phone numbers on paper. At 3 AM, you need to know exactly who to call — not @everyone in a group chat.
- The room itself: a big screen showing live order fill rate, backlog volume, and interface status; a whiteboard with the day's top 3 risks; snacks and water stocked. Nobody eats well in week one.
The week-one rhythm: three standups + severity tiers
Three standups a day, no exceptions. Morning (30 min before shift start): clear yesterday's leftovers, confirm today's wave plan. Midday check: review morning backlog and exceptions, decide whether to add hands for the afternoon. Evening retro (after close): walk the day's issue list, rate severity, assign owners and deadlines. Thirty minutes max each. Standing up.
Severity and escalation matrix — print it on the wall:
| Level | Definition | Response |
|---|---|---|
| S1 | System down / whole warehouse halted | Escalate to floor commander in 15 min; workaround within 1 hour |
| S2 | Core flow blocked (e.g., labels won't print) | Respond in 30 min; resolve or degrade within 4 hours |
| S3 | Local anomaly (a location, a document) | Resolve same day |
| S4 | Polish / UX improvements | Log to backlog; handle in week two |
When to call it: the rollback red lines
The hardest call isn't fixing a bug — it's admitting "we can't launch today." Write the red lines in advance, into the launch plan, with the owner's signature:
- Order fill rate drops below 80% with no improving trend for 2 hours;
- Backlog exceeds 1.5× daily capacity and keeps climbing;
- A core interface (ERP orders / carrier labels) is down over 4 hours with no recovery path;
- Inventory variances spread wide and counts won't converge.
Any one triggers it: the floor commander calls the stop and starts rollback. Remember: rollback isn't failure — it's loss control. Losing every customer by toughing it out for three days is the real failure. Of the launches I've run, the one we rolled back decisively went live clean two weeks later; the one we muscled through took a month of pain.
When to stand the war room down
There's a standard for that too — not "it feels okay now": three straight days with no S1/S2 issues, fill rate back to the pre-launch baseline, backlog at zero. Then one final retro: archive the issue log, hand the backlog to daily ops, downgrade the roster to on-call. Wipe the whiteboard. Stand down.
Week one of a launch is won on organization, not technology. The most stable system can't survive 40 people who don't know who to listen to. Build the war room, set the rules, and week one lands smoothly — a lesson I paid for with several all-nighters.